YandexGPT vs GigaChat vs ChatGPT: 2026 Benchmark on 80 Tasks
AI models in this article
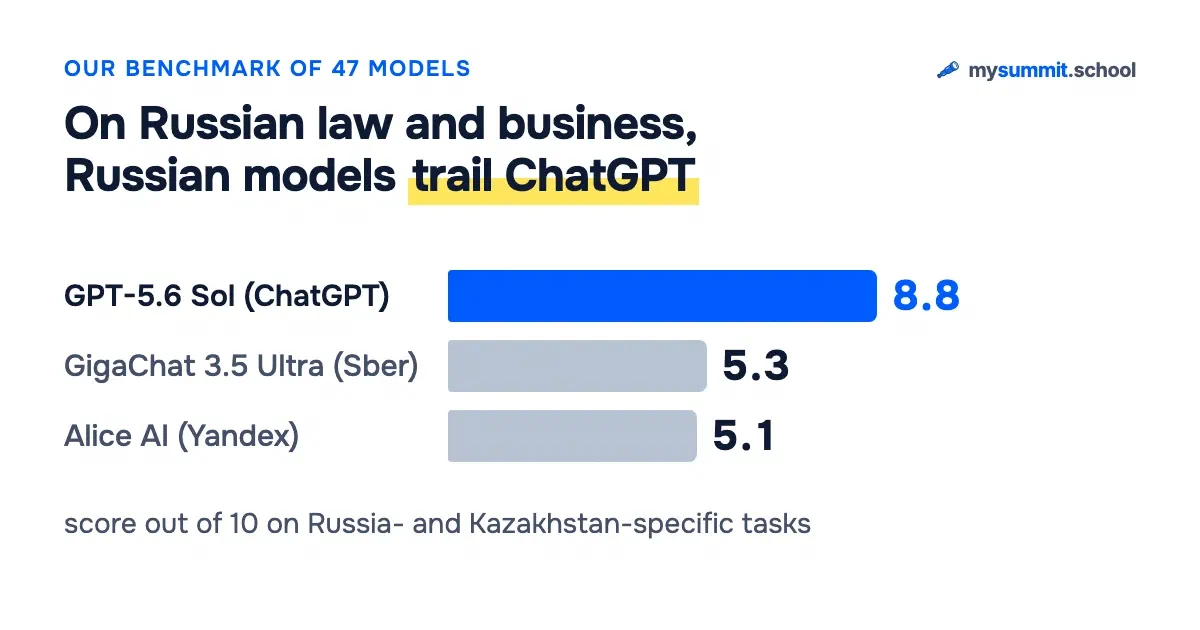
Here is the result that surprised us most. In the one task category where Russian models should have the advantage – Russian labour law, taxes, Kazakhstan’s public holidays, local business etiquette – they end up near the bottom. GPT-5.6 Sol, a model OpenAI doesn’t even offer in Russia, scores 8.8 out of 10 there, level with the best in the field. Sber’s best model, GigaChat 3.5 Ultra, scores 5.3 and ranks 42nd of 47. Yandex’s Alice AI LLM scores 5.1 and ranks 44th.
That is one line from our own benchmark: 47 models, 80 work tasks written by a manager, every answer scored by two LLM judges. We haven’t found anyone else who publishes per-task scores for GigaChat and Yandex’s models next to ChatGPT’s, so this page collects ours in one place – which model to use for what, what it costs, and whether you can use it from outside Russia at all.
Scores below are from the July 2026 run (analysis date July 17, 2026), as shown on the public benchmark page. Vendor prices and access rules were checked on November 20, 2026.
YandexGPT vs GigaChat vs ChatGPT: the comparison table
| Model | Overall score (place of 47) | Strongest task type | Weakest task type | Cost per task | Use from outside Russia |
|---|---|---|---|---|---|
| GPT-5.6 Sol (OpenAI, ChatGPT) | 9.0 (#1) | People management, 9.4 | Data analysis, 8.8 | $0.19 | Yes. Not offered inside Russia |
| GPT-5.6 Terra (OpenAI, ChatGPT) | 8.9 (#3) | Feedback analysis, 9.3 | Russia/Kazakhstan specifics, 8.6 | $0.098 | Yes. Not offered inside Russia |
| GPT-5.6 Luna (OpenAI, ChatGPT) | 8.6 (#7) | People management, 9.1 | Russia/Kazakhstan specifics, 7.9 | $0.029 | Yes. Not offered inside Russia |
| DeepSeek V4 Flash on Yandex Cloud | 7.3 (#32) | Feedback analysis, 8.2 | Russia/Kazakhstan specifics, 6.2 | $0.023 | Retired by Yandex on November 15, 2026 |
| GigaChat 3.5 Ultra (Sber) | 6.9 (#37) | Decisions under uncertainty, 8.1 | Russia/Kazakhstan specifics, 5.3 | $0.011 | Open weights (MIT) anywhere. Hosted API: foreign sign-up not documented |
| Alice AI LLM (Yandex, successor to YandexGPT) | 6.3 (#43) | Feedback analysis, 6.9 | Russia/Kazakhstan specifics, 5.1 | $0.020 | Chat: yes, Russian and English. API: Yandex Cloud, USD billing after approval |
| GigaChat 2 Max (Sber) | 4.2 (#47) | Data analysis, 4.7 | Russia/Kazakhstan specifics, 3.6 | $0.013 | Sber API. Eligibility for non-residents not documented |
Scores are on a 1–10 scale, averaged over 80 tasks. Models less than 0.3 points apart are statistically tied, so the place number is a position, not a podium: Sol, Terra and three other models share the top group, and Alice AI shares places 43–45 with two others. “Cost per task” is what one benchmark task (prompt plus answer) cost through the API at the prices in effect when we tested in July. Two of those prices have since dropped: OpenAI cut Terra by 20% and Luna by 80% on July 30, so today Luna costs roughly $0.006 per task and Terra about $0.078.
Three things to take from the table before the details.
The gap is large. The best model you can rent from a Russian provider ranks 32nd, and the best Sber model trails GPT-5.6 Sol by more than two points out of 10. Our benchmark treats gaps under 0.3 points as measurement noise, and this one is about seven times that.
Russian models are not cheap. GigaChat 3.5 Ultra costs about $0.011 per task. GPT-5.6 Luna, at today’s price, costs about half that and scores 1.7 points higher.
“YandexGPT” in 2026 mostly means Alice AI. Yandex still sells YandexGPT Pro 5.1 through its AI Studio, but its flagship and the model behind the Alice assistant is Alice AI LLM. We retested Alice in July; YandexGPT Pro 5.1 only went through our earlier March round (more on that below).
Which model for which kind of work
The overall score hides a lot. Each model answered 10 tasks in each of 8 categories, and the profiles differ more than the ranking suggests. Here is what the per-category numbers and the judges’ comments say.
Decisions under uncertainty: GigaChat’s best showing
This category covers decisions with incomplete data: allocating a budget without full numbers, a hiring call with mixed signals, prioritising when stakeholders disagree. It is where GigaChat 3.5 Ultra looks most like a modern model: 8.1, rank 23 of 47, level with both versions of DeepSeek V4 Flash (bought directly 8.0, on Yandex Cloud 7.9). The judges credited it with working through strategic alternatives and risks, and docked it for overlooking outside factors such as investor interests and network effects.
The OpenAI models are still well ahead: Sol and Terra both score 9.1, ranks 2 and 3. Alice AI scores 6.9 here, rank 43.
Good scripts and thin plans in people management
Hiring, one-on-ones, performance reviews, a difficult conversation with an employee. GPT-5.6 Sol scores 9.4 here, its best category and level with the best result in the field.
Alice AI scores 6.8 (rank 42), but this is the category where the judges liked it most: “excellent scripts for difficult conversations and high empathy”, let down by “superficial action plans”. If you need wording for a hard talk in Russian, Alice is usable. If you need a plan for what happens after it, it isn’t.
GigaChat 3.5 Ultra is weaker here than its overall rank suggests: 6.3, rank 45. The judges’ verdict was basic interview plans and templates with surface-level advice and no clear evaluation criteria.
Data analysis: check every figure
Sales analysis, budget variance, process metrics. Even in one of its two lowest categories, GPT-5.6 Sol scores 8.8 (rank 3).
Both Russian models make arithmetic mistakes that the judges called out explicitly. GigaChat 3.5 Ultra (7.5, rank 29) “inflates financial figures” and “invents baseline numbers”. Alice AI (6.4, rank 43) makes arithmetic errors and leaves out taxes. Whatever you use a Russian model for, don’t let it be the last step before a number goes into a report.
Feedback analysis, where Alice’s best score still ranks 44th
Customer complaints, engagement surveys, meeting sentiment. Alice AI’s best category score is 6.9, which puts it 44th. DeepSeek V4 Flash on Yandex Cloud did better here (8.2, rank 27), and GigaChat 3.5 Ultra scored 7.4 (rank 42) with counting errors in the judges’ notes.
Automation and code are not their job
Data-extraction scripts, API integrations, report automation. GigaChat 3.5 Ultra scored 6.3 (rank 38): the judges wrote that it proposes sensible architecture and then replaces working code with placeholder stubs. Alice AI scored 5.8 (rank 42) with syntax errors and broken code. A developer would not pick either for this, and the scores agree.
Invented facts in information search and compliance
In information search, Alice AI (6.1, rank 44) was penalised for outdated data and factual hallucinations, GigaChat 3.5 Ultra (7.0, rank 34) for distorting or inventing market statistics. In the corporate requirements and risks category, which covers compliance and contract risk, both misstated penalty amounts and cited laws that don’t apply: GigaChat 3.5 Ultra scored 7.0 (rank 33), Alice AI 6.5 (rank 42).
Russia and Kazakhstan specifics: the category Russian models lose
Back to the result from the top. This category is Russian labour law (for example, terminating a protected employee), Kazakhstan tax changes for 2026, public holiday schedules and the formality of Russian business letters. It is the weakest category for every Russian model in the table.
The judges called GigaChat 3.5 Ultra’s advice here “dangerous”: it cited laws no longer in force, got Kazakhstan’s rescheduled days off wrong and gave false information about maternity leave rights in Russia. Its trustworthiness score in this category was 4.5 out of 10. Alice AI was penalised for “critical errors in legislation”, outdated rules and refusals on sensitive topics, though the judges did credit it with a feel for the cultural context.
The OpenAI models are not flawless here either. Terra’s notes mention errors in Kazakhstan’s tax specifics, and Luna drops to 7.9 – its worst category. But 8.8 for Sol against 5.3 for the best Sber model is not a close call. Knowing the language and knowing the current version of the law turn out to be different skills, and the second one depends on how fresh and how well-checked the training data is.
Where each model falls short
GigaChat 3.5 Ultra is real progress for Sber. In the same July run, the previous generation sits at the very bottom: GigaChat Ultra (the March 2026 release) at 4.8, rank 46, and GigaChat 2 Max at 4.2, rank 47 – last. Going from 4.2 to 6.9 within one product line is a big jump. It is also the only model on this list whose weights you can download and run yourself. What holds it back is accuracy: numbers, laws, code. One more data point from our March test: turning on GigaChat Ultra’s reasoning mode made results 3.3% worse across 32 tasks.
Alice AI LLM barely moved: the version we retested in July scored 6.3 against 6.0 for the earlier Alice AI LLM, a difference inside our 0.3-point noise band. Its writing is clean and well structured, which matches what we saw in a separate prompting experiment: there, only 75% of Alice’s verifiable claims were correct against 87% for GPT-5.4, but a simple answer template that asks for a “limitations” section beat a plain question 76% of the time. Prompting narrows the gap; it doesn’t close it.
YandexGPT Pro 5.1 was only tested in our March 2026 round, which used a different scale (1–5) and 4 tasks per category, so its numbers don’t mix with the table above. There it placed 45th of 54 with 3.1, below Alice AI LLM (38th, 3.9); GPT-5.4, near the top of that round, scored 4.9. In our YandexGPT review we noted that in half of the information-search tasks it refused outright, citing a lack of current data. Since Yandex now positions Alice AI as its flagship, we did not retest it.
DeepSeek V4 Flash on Yandex Cloud is a Chinese open-weight model hosted by Yandex inside Russia. It was the best option in Yandex’s catalogue (7.3), statistically tied with the same model bought directly from DeepSeek (7.5). But it cost 27 times more per task ($0.023 against $0.00084), and Yandex retired it on November 15, 2026 in favour of DeepSeek V4.1 Flash, which we haven’t scored yet.
GPT-5.6 Sol, Terra and Luna sit at or near the top of nearly every category, and their weak spots are the same across all three: fewer exact figures and source references than the judges wanted, and errors on Kazakhstan taxes. For anyone in Russia the practical problem is access: Russia is not on OpenAI’s list of supported countries for ChatGPT or the API.
GigaChat and YandexGPT API prices, free tiers and access
We checked everything in this section on vendor pages on November 20, 2026. The rules differ a lot between vendors, and some of what a foreign reader needs to know isn’t documented at all.
OpenAI (ChatGPT, API). API prices per million tokens: Sol $5 input / $30 output (on promotion at $4 / $20 until November 30, 2026), Terra $2 / $12 and Luna $0.20 / $1.20 since the July 30 price cut (OpenAI, OpenAI community announcement). Russia is not a supported country.
Yandex (Alice AI, YandexGPT). The Alice AI chat is free, and Yandex’s help page says it is available everywhere and answers in English “as well as in Russian” – that is Yandex’s claim, and we haven’t tested it. The paid Alice Plus features are limited to Russia and Belarus.
For the API, Yandex Cloud accepts non-residents (page updated May 7, 2026): you pay in US dollars by card or wire transfer, a Yandex representative approves the billing account within up to three business days, and some countries can’t sign up at all (the page doesn’t say which). International API prices per million tokens, excluding VAT: Alice AI LLM $4.10 input / $9.84 output, Alice AI LLM Flash $0.82 / $1.64, YandexGPT Pro 5.1 $6.56 both ways. Inside Russia the same models cost 500 / 1,200 rubles and 800 / 800 rubles per million tokens, VAT included. The price list mentions no general free tier. Alice AI LLM Flash is new and hasn’t been through our benchmark.
Sber (GigaChat). GigaChat 3.5 Ultra is sold through Cloud.ru Foundation Models at 96.22 rubles per million input tokens and 288.6 rubles per million output, with a 262K context. Its weights are on Hugging Face under the MIT license, tagged for Russian and English. Sber’s own API gives individuals 365 million free tokens for 12 months (page updated October 7, 2026), split across the Lite, Pro, Max and GigaChat 3 Ultra models – 3.5 Ultra is not included. Paid packages start at 1,300 rubles for 20 million Lite tokens. What we could not verify: whether foreigners can register for giga.chat, the Sber API or Cloud.ru. None of the official pages we read says either way, so plan on running the open weights if you are outside Russia.
The chart plots each model’s July cost per task against its score. It uses the prices before OpenAI’s July 30 cut, so Luna and Terra look more expensive on it than they are today.
Which one should you use
A company inside Russia that needs data to stay in the country
OpenAI doesn’t serve Russia, so the choice is between domestic options. On our data the order was DeepSeek V4 Flash hosted by Yandex (7.3), then GigaChat 3.5 Ultra (6.9), then Alice AI (6.3). Yandex has just replaced that DeepSeek model with V4.1 Flash, which we haven’t tested, so for now GigaChat 3.5 Ultra is the strongest Russian-hosted model with a current score. It is also the only one you can run on your own servers, which matters if “data stays in Russia” means “data stays in our building”. Alice AI makes sense mainly if you already work inside Yandex 360.
Whichever you choose, the weakest category is the same for all of them: Russian law, taxes and regulations. Have a person check every legal reference and every number.
A foreign team researching the Russian market
Use the model you already trust for analysis. In our data, GPT-5.6 Sol handled Russian labour law, taxes and business etiquette better than any Russian model, and Terra and Luna came close on most categories at a fraction of the price. Then open the free Alice AI chat. According to Mediascope, Alice is the most widely used AI assistant in Russia, so what it says about a local brand, a local law or a news event shows you what Russian users are being told. Check its facts somewhere else before you rely on them.
A developer who wants a cheap API
If Russian hosting doesn’t matter, neither Russian vendor wins on price. DeepSeek V4 Flash bought directly costs $0.00084 per task at a score of 7.5, and GPT-5.6 Luna about $0.006 at 8.6 since the price cut. GigaChat 3.5 Ultra costs about $0.011 per task at 6.9. If you need a Russian model for a Russian-language product, the cheapest way to try it is the open weights (if you have the hardware for a 432-billion-parameter model) or Sber’s free annual token allowance on the older models. Alice AI LLM Flash, at $0.82 / $1.64 per million tokens, is worth testing once it has a score; we haven’t measured its quality yet.
Picking a model is half of the job. The other half is how you ask: the same structured template that beat a plain question for Alice 76% of the time works on any model. And a convincing answer can still be wrong in ways that are easy to miss, as every Russian model in this benchmark showed with numbers and laws. Our free English module is built around exactly that: nine lessons, each a real work task.
How we tested, and what it doesn’t tell you
Every model got the same 80 tasks, 10 in each of 8 categories, written the way a middle manager with a team of 5–30 people would write them: no prompt engineering, no special techniques. Two LLM judges, Claude Opus 4.6 and Gemini 3.1 Pro, scored each answer from 1 to 10 with equal weight, on six criteria: accuracy (25% of the score), relevance (20%), actionability (20%), transparency, efficiency and trustworthiness (10% each). Neither judge comes from OpenAI, so the GPT models were not graded by their own vendor. The full methodology and every model’s page are on the benchmark page, and our explainer on how LLM benchmarks work covers why any benchmark deserves some suspicion.
The limitations that matter for this comparison:
- All 80 tasks are in Russian. We measured how well models do Russian-language work, which favours Russian models if anything. We did not measure English-language quality.
- Each score comes from a single run per task, so small gaps are noise. Gaps under 0.3 points count as ties. The gaps between the GPT-5.6 models and the current Russian flagships (GigaChat 3.5 Ultra and Alice AI) are 1.7–2.7 points; the gap between the two DeepSeek V4 Flash versions (under 0.2) is not a finding.
- Both judges are large Western proprietary models. If they shared a bias against a style of answer common in Russian models, our design would not catch it.
- The scores are from July 2026. Yandex retired DeepSeek V4 Flash on November 15, and our November wave, which includes GPT-6.1 and other new releases, has not been scored yet. Vendors update models without notice.
- Per-task cost is measured at July prices; we’ve adjusted it in the text where a vendor has changed prices since.
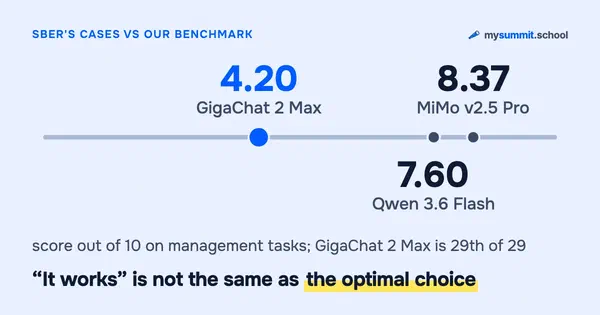
For a deeper look at a single vendor, see our reviews of GigaChat and YandexGPT and Alice AI, our check of Sber’s 40 GigaChat business cases against the benchmark, and the wider comparison of GenAI tools.
Related articles
Questions
Is YandexGPT better than ChatGPT?
Is Alice AI the same as YandexGPT?
What is the best Russian AI model?
Can I use GigaChat or Alice AI from outside Russia?
How much does the GigaChat API cost?
Is YandexGPT free?

18 years leading engineering teams. Founder of mysummit.school. 700+ graduates at Yandex Practicum and Stratoplan.